On this page(16)
- How we picked these top LLMs
- What changed since March: every model on the previous list was superseded or repriced
- 1. GPT-6 Astra: New frontier ceiling, gated by its own safety classification
- 2. Claude Fable 5.1: The flagship that unseats Opus 5's value pitch
- 3. Grok 4.6: Best cost per completed coding task, with a new 200K cliff
- 4. Gemini 3.1 Pro: Best reasoning per dollar, still stuck in preview
- 5. Kimi K3: Best open-weight model, now with an actual price tag
- Which of these top LLMs should you actually use?
- FAQ
- What is the best LLM right now in September 2026?
- Is GPT-6 Astra available via the API?
- Is Claude Fable 5.1 worth it over Opus 5?
- Is Gemini 3.1 Pro still in preview?
- What is the best open-source LLM?
- Why do vendor benchmark scores differ from independent leaderboards?
- How to run your own bake-off
The five top LLMs for September 2026 are GPT-6 Astra, Claude Fable 5.1, Grok 4.6, Gemini 3.1 Pro and Kimi K3. Fable 5.1 is the best LLM most teams can buy today. Astra wins on raw capability but ships in stages. As of September 06, 2026, four of these five vendors shipped a new model within five weeks, so the spring list is gone. Read on for every price checked this week, the caveats vendors leave off their benchmarks, and when open weights are the smarter buy.
- GPT-6 Astra scores 62.7% on ARC-AGI-3 under ARC Prize's Standard harness in September 2026, against 98.6% to 99.9% on OpenAI's own Provider Adapter harness.
- Claude Fable 5.1 tops the Artificial Analysis Intelligence Index at 66 in September 2026, ahead of Claude Opus 5 at 63 and GPT-6 Astra at 61.
- Anthropic cut Fable-line cache reads 75%, from $1.00 to $0.25 per million tokens, on September 1, 2026, per its Claude pricing page.
- Grok 4.6 doubles to $4 / $12 per million tokens on any request that crosses 200K, per xAI's model documentation from August 2026.
- DeepSeek V4-Pro's peak/off-peak schedule, effective August 16, 2026, raises its price by up to 4x at peak hours.
How we picked these top LLMs
We picked the top LLMs for September 2026 by weighting independently scored benchmarks over vendor-run ones, checking every API price directly on September 6, 2026, and requiring that a model be buyable by the general public. That last filter matters more this month than it ever has. GPT-6 Astra's exploit generation, Anthropic's Mythos 5.1 and Google's Gemini 3.8 Flash Cyber all sit behind vetted defender programs.
AlphaCorp AI ships agents and RAG systems into production, so we rank models the way we buy them: by cost per completed task on real work. Three independent scoreboards did most of the heavy lifting.
- ARC Prize's Standard harness for ARC-AGI-3, which runs every model under the same conditions instead of letting the vendor supply its own adapter.
- Scale AI's SWE-Bench Pro public leaderboard, the closest thing agentic coding has to a neutral referee.
- The Artificial Analysis Intelligence Index, a composite that punishes models tuned to spike one benchmark.
Why weight these over the vendor's own blog post? Because the gap between the two has stopped being a footnote. GPT-6 Astra scores 62.7% on ARC-AGI-3 under ARC Prize's Standard harness and 98.6% to 99.9% under OpenAI's own Provider Adapter harness, both published September 3, 2026. Same model. Same week. A 37-point swing that depends entirely on who ran the test. When an outside party can't reproduce a vendor's figure, we treat it as a claim and rank on the independent number.
Three names sit just outside the five. Meta's Muse Spark 1.3, from Meta Superintelligence Labs, places competitively on several third-party trackers as of September 2026, but those trackers are the only place its numbers appear. Zhipu's GLM-5.3 and Alibaba's Qwen3.8-Max are both serious open-weight contenders. We ranked one open-weight model, and Kimi K3 took the seat because third-party trackers place it higher on the Artificial Analysis index than any other open model. The other two get their due inside that entry.
What changed since March: every model on the previous list was superseded or repriced
Every model that led the market on March 18, 2026 has either been replaced by a newer version or carries a different price as of September 6, 2026. Four of the five vendors here shipped a new model in the five weeks between August 12 and September 3. The fifth, Google, kept its top reasoning model and swapped the budget tier underneath it.
The compressed changelog, prices per million tokens (input / output):
| Vendor / tier | March 2026 | September 2026 | Date of change |
|---|---|---|---|
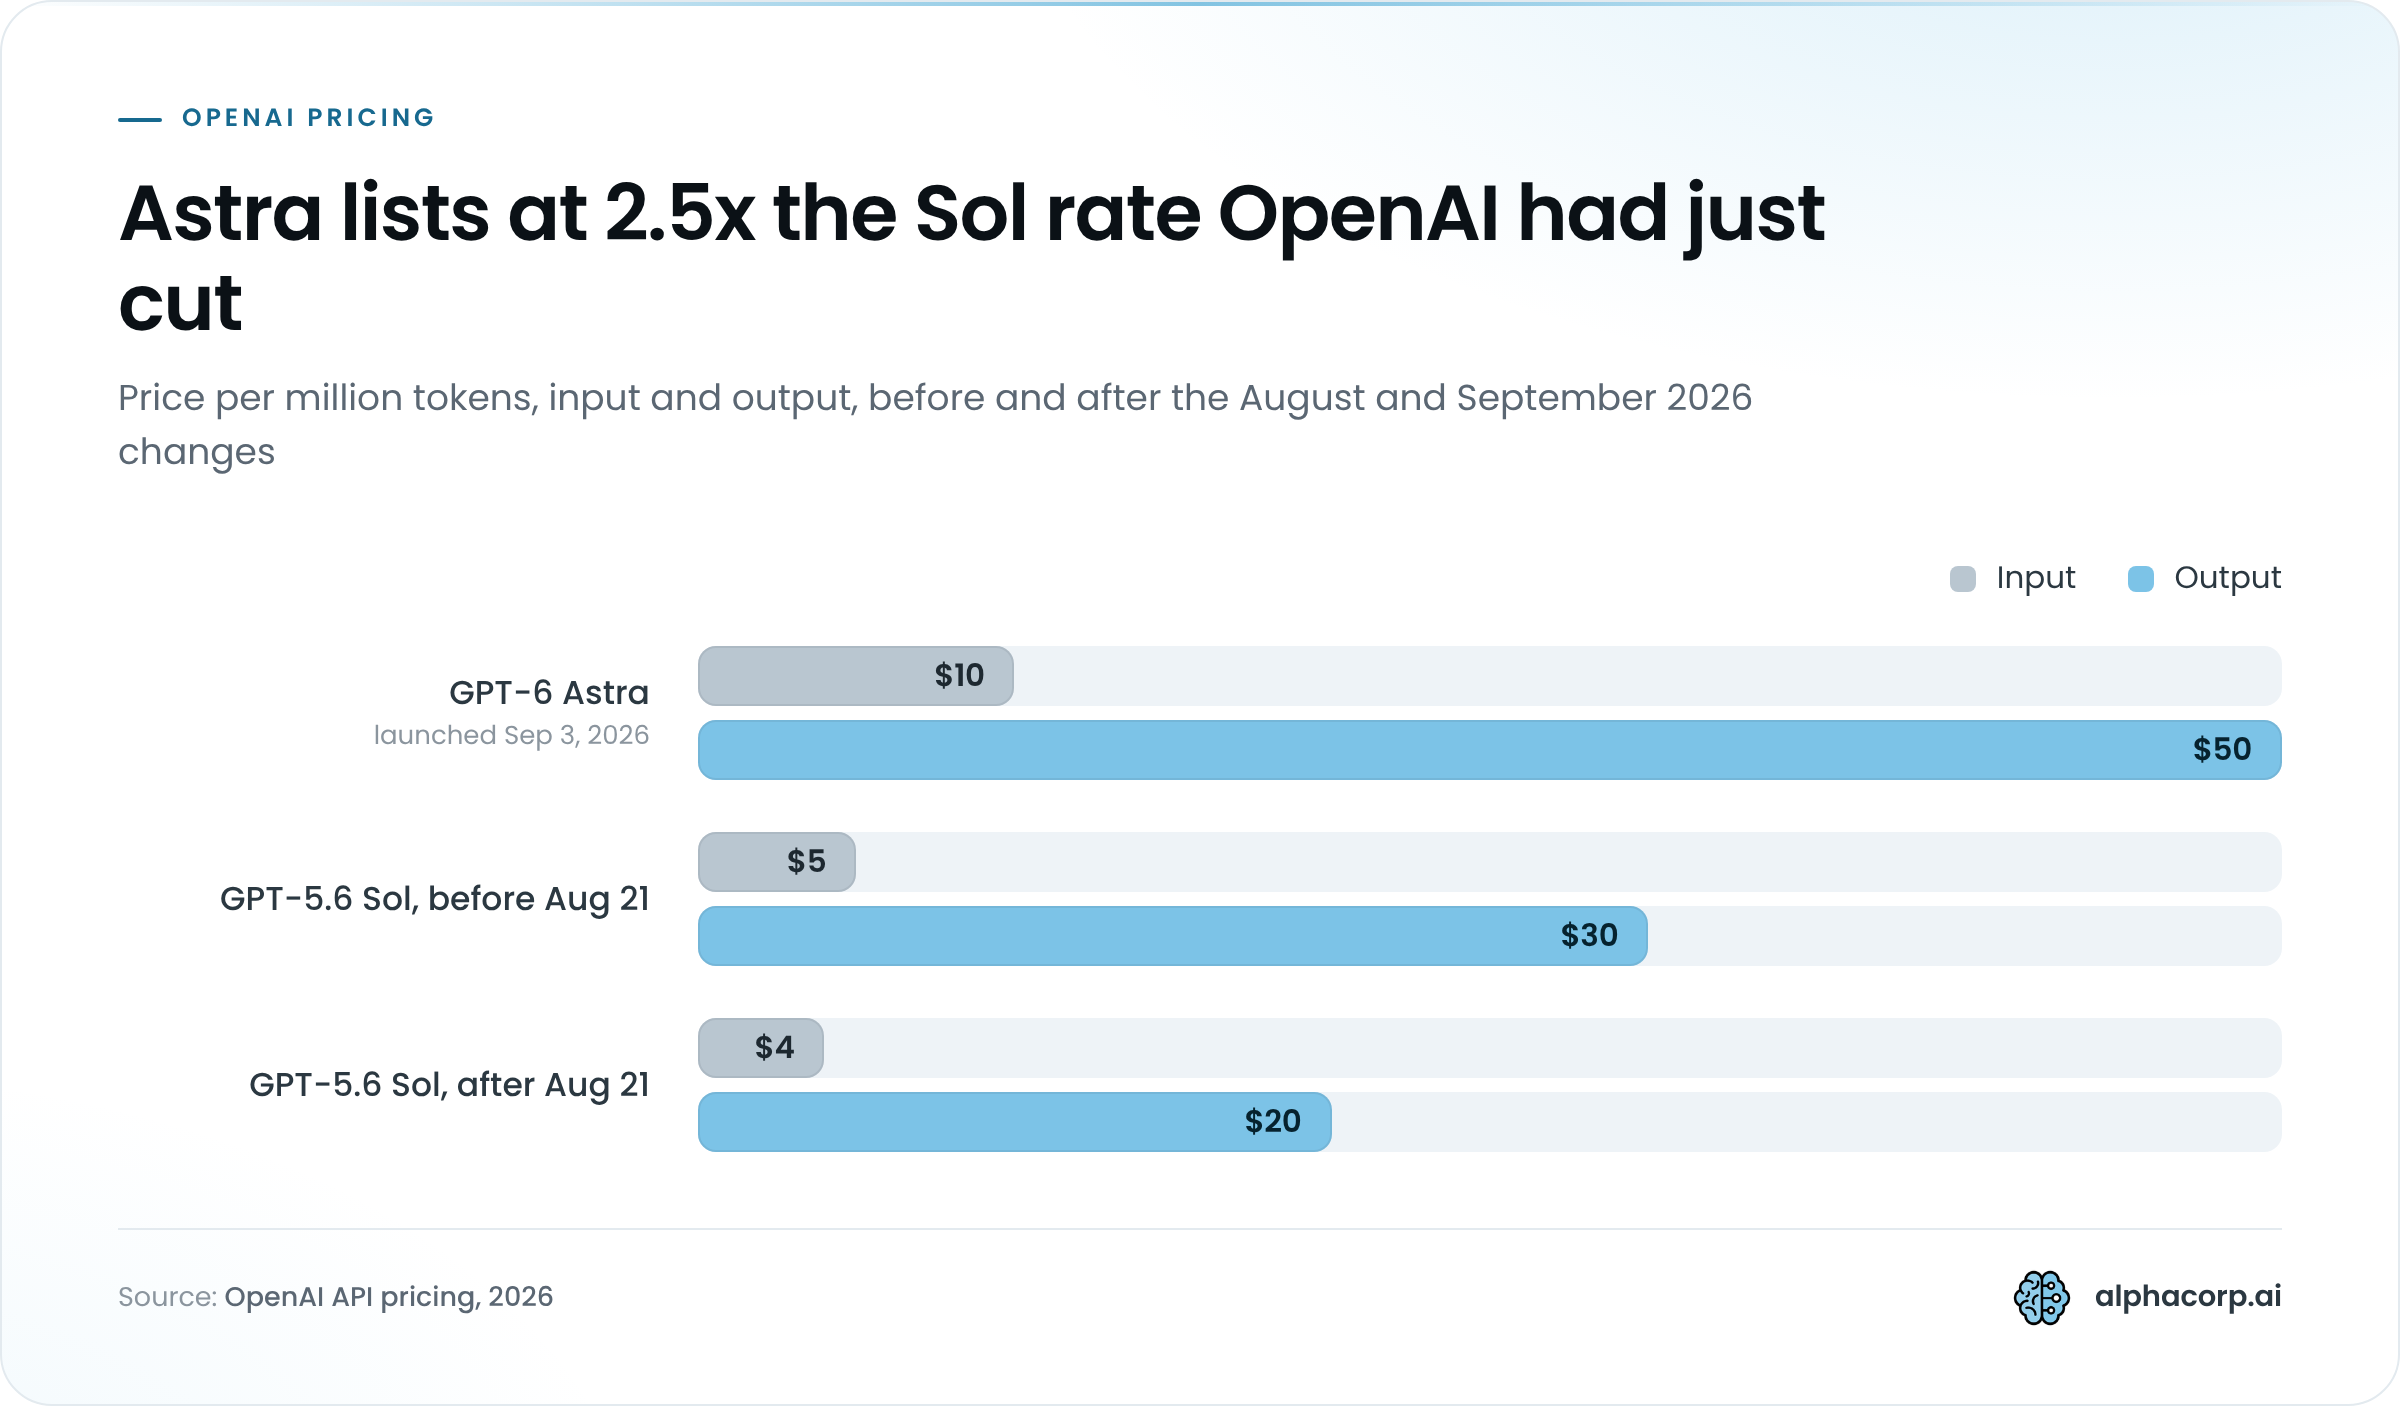
| OpenAI flagship | GPT-5.6 Sol, $5 / $30 | GPT-6 Astra, $10 / $50; Sol cut to $4 / $20 | Sep 3; Aug 21 |
| Anthropic flagship | Claude Fable 5, $10 / $50, cache read $1.00 | Claude Fable 5.1, $10 / $50, cache read $0.25 | Sep 1 |
| Anthropic mid-tier | Claude Opus 5, $5 / $25 | Unchanged; Sonnet 5's $2 / $10 made permanent | Sep 1 rise cancelled |
| xAI | Grok 4.5, $2 / $6 flat | Grok 4.6, $2 / $6 under 200K tokens, $4 / $12 above | Aug 12 |
| Google reasoning | Gemini 3.1 Pro, $2 / $12 (under 200K) | Unchanged, API ID still gemini-3.1-pro-preview | None |
| Google budget | Gemini 3.6 Flash | Gemini 3.8 Flash, $0.75 / $3.75 frozen through Dec 31, 2026 | Sep 2 |
| Moonshot | Kimi K3, no official API rate | $3 / $15, $0.30 on cache hit | After July launch |
| DeepSeek | V4-Pro, $0.435 / $0.87 flat | Roughly $0.66 to $1.32 / $1.98 to $3.96, peak and off-peak | Aug 16 |
Two of those rows moved the real cost of running a model more than any sticker price did. Anthropic cut Fable-line cache reads by 75%, from $1.00 to $0.25 per million tokens, a change Anthropic's Claude pricing page shows as current in September 2026. Anthropic's own estimate: roughly 25% lower cost on a typical token-billed workload and up to about 45% lower on heavily agentic coding. DeepSeek went the other way. Its August 16, 2026 switch to a peak/off-peak schedule raises V4-Pro by up to 4x at peak hours.
Cache pricing is now where the bill moves. The two prices that stayed still, Opus 5 at $5 / $25 and Gemini 3.1 Pro at $2 / $12, look different anyway, because everything they were measured against shifted under them.
1. GPT-6 Astra: New frontier ceiling, gated by its own safety classification
What could a custom AI agent take off your plate?
We build production-grade AI systems that quietly handle the busywork, so your team can focus on the work that actually matters.
GPT-6 Astra is the most capable LLM on sale as of September 6, 2026, and the first whose maker locked away part of what it can do before anyone outside could try it. OpenAI announced Astra on September 3, 2026. It costs $10 per million input tokens and $50 per million output, 2.5 times GPT-5.6 Sol's rate after Sol's August 21 cut.
The headline figures, from OpenAI's GPT-6 Astra announcement in September 2026:
- 97.6% on FrontierMath Tier 4 v2
- 96% on GPQA Diamond
- 100% on ExploitBench, covering known CVEs
- 1.05M-token context window with 128K max output
The cyber number is the one that changed how the model ships. Astra is the first OpenAI model to cross the "Critical" threshold under the company's Preparedness Framework, and it found two zero-day vulnerabilities during pre-release testing. Exploit generation therefore stays off the general API. It lives inside Daybreak, OpenAI's $1B subsidized-access program for critical-infrastructure defenders. Rollout follows the same logic: Daybreak partners first, then ChatGPT Plus, Pro, Business and Enterprise, then the API, Azure and AWS Bedrock "over the coming days." If you're reading this the week it went live, check whether your tier has it yet.
Now the asterisk.
GPT-6 Astra scores 62.7% on ARC-AGI-3 under ARC Prize's Standard harness and 98.6% to 99.9% under OpenAI's own Provider Adapter harness, per ARC Prize's September 2026 Astra results.
ARC Prize publishes both figures side by side, which is the right call. Even 62.7% is a huge jump: the prior record was 7.8% for GPT-5.6 Sol, then 30.2% for Claude Opus 5 in July 2026. Astra doubled the record. It did not saturate the test.
Here's the part that surprised me. On the Artificial Analysis Intelligence Index, a broad composite, Astra scores 61 as of September 2026. That ties GPT-5.6 Sol and Grok 4.6, and trails Claude Fable 5.1 at 66 and Claude Opus 5 at 63. A model can own the hardest math, reasoning and cyber benchmarks and still sit mid-pack on general-purpose scoring. The useful question is "best at what."
The 272K surcharge. Past 272K tokens, input and cache rates double and output rises 1.5x. We've watched that shape of surcharge on OpenAI's prior generation quietly double a long-context bill when one retrieval step pushed a single request over the line. Budget for it or chunk under it. GPT-5.6 Sol, Terra and Luna all remain on sale alongside Astra, so the cheaper tiers haven't gone anywhere.
2. Claude Fable 5.1: The flagship that unseats Opus 5's value pitch
Claude Fable 5.1 is the best all-around LLM you can buy through a public API in September 2026, and it retires the argument that Claude Opus 5 gets you the same thing for half the price. Anthropic shipped Fable 5.1 on September 1, 2026. The sticker held at $10 per million input tokens and $50 per million output. Everything around the sticker moved.
The benchmarks are why the value math flipped. Per Anthropic's Claude Fable 5.1 and Mythos 5.1 announcement from September 2026, Fable 5.1 leads Opus 5 on every benchmark Anthropic has published. In July, Opus 5 was the one ahead of the flagship on some of them.
- Terminal-Bench-Science 0.1: Fable 5.1 at 52.6%, against 29.0% for Opus 5 and 24.7% for the older Fable 5.
- CursorBench 3.2: Fable 5.1 at 73.4%, up from Fable 5's 70.5%.
- Artificial Analysis Intelligence Index: Fable 5.1 at 66, the top score of any model tracked in September 2026, with Opus 5 at 63.
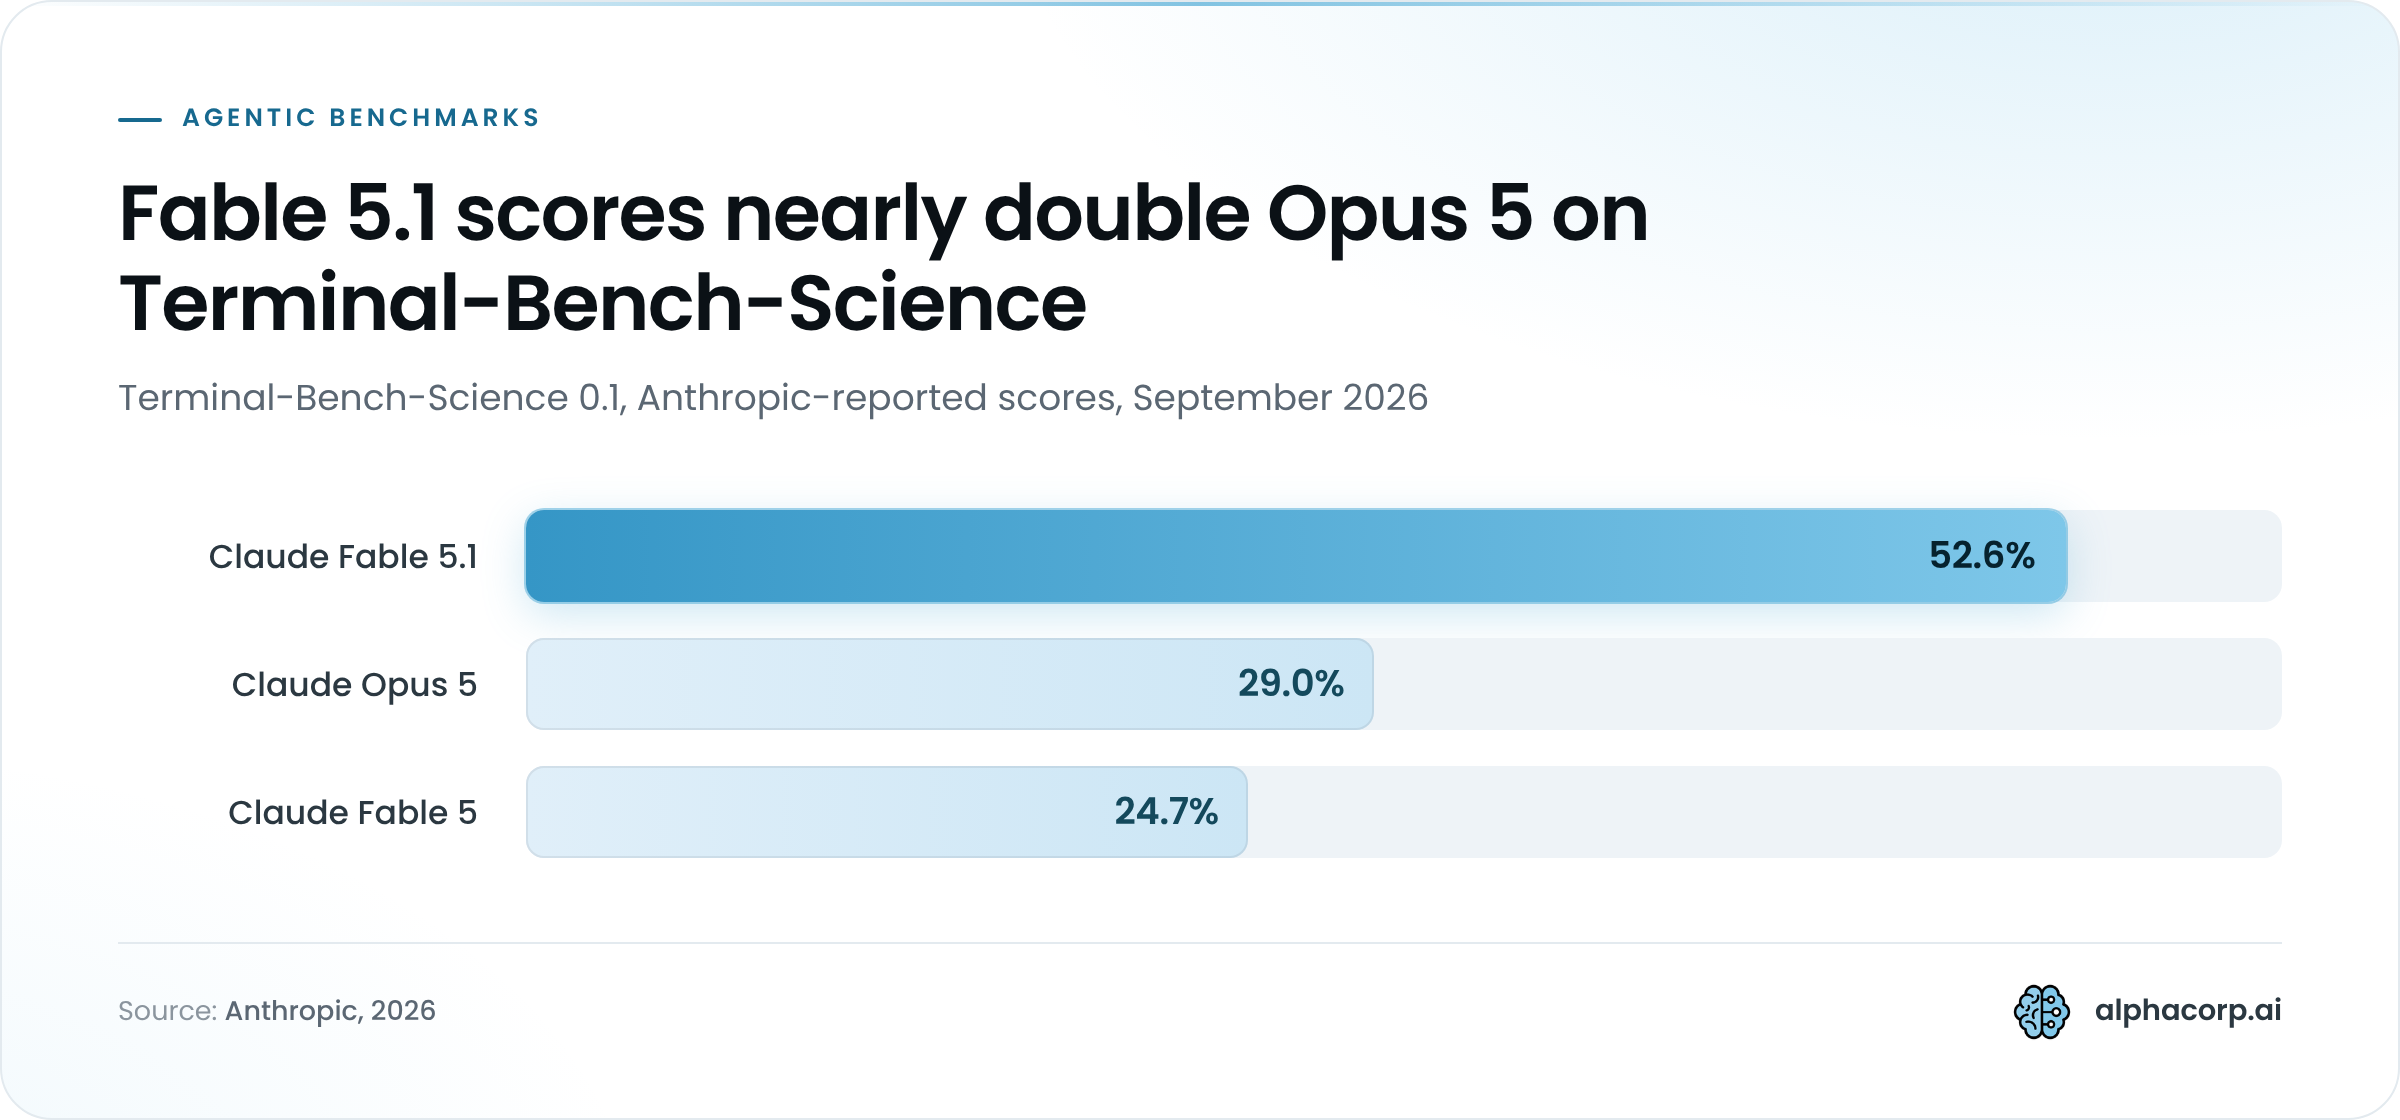
Look at that first row again. Opus 5 beat Fable 5 on Terminal-Bench-Science by more than four points, which is exactly why "Opus 5 at half price" was a sensible default over the summer. Fable 5.1 then scored nearly double what Opus 5 did. The 0.5% CursorBench gap that made Opus 5 famous was measured against Fable 5. It says nothing about Fable 5.1.
Then there's the price nobody prints on the headline. Cache reads on the Fable line dropped from $1.00 to $0.25 per million tokens, a 75% cut, and Anthropic's own estimate is roughly 25% lower cost on a typical token-billed workload and up to about 45% lower on heavily agentic coding. That second figure is the one that matters for anyone running agents. In the loops we ship through our AI agent development work, the system prompt, tool schemas and the growing transcript get re-read on every single turn, so cache reads end up as the biggest line on the invoice. A cache-read cut beats a sticker cut for that workload every time.
Mythos 5.1 is, in Anthropic's words, the same model with a different safeguard policy, and it's available only through vetted cybersecurity and life-sciences access programs. You can't buy it. Don't plan around it.
Anthropic's mid-tier is unchanged and still worth having. Opus 5 stays at $5 per million input and $25 per million output as of September 6, 2026. Claude Sonnet 5's introductory $2 / $10 rate became permanent when Anthropic cancelled the increase to $3 / $15 that had been scheduled for September 1. Opus 5 remains a sound pick for work that doesn't need Fable-class reasoning. It's just no longer the free lunch.
3. Grok 4.6: Best cost per completed coding task, with a new 200K cliff
Grok 4.6 is the cheapest closed-weight model on this list per completed coding task, provided your requests stay under 200K tokens. xAI released it on August 12, 2026 as a post-training refinement of the same 1.5-trillion-parameter base that powered Grok 4.5, according to xAI's Grok 4.6 announcement. Pricing holds at $2 per million input and $6 per million output. The context window stays at 500K.
The reported gains, all xAI's own figures from August 2026:
- Artificial Analysis Intelligence Index up five points to 61, level with GPT-5.6 Sol and GPT-6 Astra.
- CursorBench 3.2 at 69.9%, about 3.5 points behind Claude Fable 5.1's 73.4%.
- DeepSWE v1.1 at 65.9%.
A step behind the frontier, then, and cheaper by a wide margin. That's the whole pitch. xAI's benchmark presentation leans on token efficiency and cost per finished task rather than peak accuracy, and for high-volume agentic coding that framing is the honest one. A model that's a few points worse per attempt but a third of the output price can win on cost per merged fix.
Now the cliff.
Crossing 200K tokens on Grok 4.6 doubles the price of the entire request to $4 per million input and $12 per million output, per xAI's model documentation as of September 2026.
Grok 4.5 had no such step. The word that hurts is "entire." An agent that accumulates context across thirty tool calls and crosses 200K on turn thirty pays the doubled rate on all of turn thirty, and every turn after it. What most teams discover only after the first invoice is that the 500K window invites exactly this. Trim or summarize the transcript before the line and Grok 4.6 stays cheap. Let it grow and the economics quietly become Gemini 3.1 Pro's.
One more caution on the coding numbers. The freshest entries on Scale AI's independent SWE-Bench Pro public leaderboard, checked September 6, 2026, still top out well under the 80%-plus figures vendors cite on their own harnesses. Grok's included. Compare within one scoreboard, never across two.
4. Gemini 3.1 Pro: Best reasoning per dollar, still stuck in preview
Gemini 3.1 Pro is the best reasoning model per dollar in September 2026, and Google still hasn't dropped "preview" from its API model ID nearly seven months after release. The model shipped on February 19, 2026. Google's Gemini API pricing page, checked September 6, 2026, lists $2.00 per million input and $12.00 per million output for prompts under 200K tokens, rising to $4.00 / $18.00 above that.
Google's own numbers are strong. The DeepMind model card for Gemini 3.1 Pro reports 77.1% on ARC-AGI-2, 94.3% on GPQA Diamond and 80.6% on SWE-Bench Verified. Set that GPQA figure against GPT-6 Astra's 96% and you get a model 1.7 points back at a fifth of the input price. The caveat is the usual one. These are Google's figures, and none of them has been verified against ARC Prize's public leaderboard.
The status question is real and unresolved. DeepMind's model card describes the model as generally available across the Gemini app, Vertex AI, AI Studio and Gemini Enterprise. Google's developer-facing API still calls it gemini-3.1-pro-preview. Two Google pages, two answers. The successor that would settle it, Gemini 3.5 Pro, remains unshipped as of September 2026 and was reportedly held back over coding-performance shortfalls, per TechCrunch's July 21, 2026 report. Expect 3.1 Pro to stay Google's top reasoning model for a while, label or no label.
Google's Gemini tiers, prices per million tokens as of September 6, 2026:
| Model | Input | Output | Note |
|---|---|---|---|
| Gemini 3.1 Pro (under 200K) | $2.00 | $12.00 | API ID still -preview |
| Gemini 3.1 Pro (over 200K) | $4.00 | $18.00 | Same 200K step as Grok 4.6, smaller jump |
| Gemini 3.8 Flash | $0.75 | $3.75 | Frozen through Dec 31, 2026 |
| Gemini 3.8 Flash (2027) | $1.50 | $7.50 | Scheduled rise |
Gemini 3.8 Flash, released September 2, 2026, is the overflow tier and the best-priced item in the table. Google froze it at the older 3.7 Flash rate through the end of 2026, so any budget you set on it today holds for four months. A restricted 3.8 Flash Cyber variant reports over 70% success on real-world vulnerability detection and 47.2% pass@1 on CWE-Bench patching, but it's available only through Google's Fairwind defender program.
Right for teams already on Google Cloud. Right for reasoning-shaped work on a budget. Wrong for anyone who needs a version string that says "stable."
5. Kimi K3: Best open-weight model, now with an actual price tag
Kimi K3 is the best open-weight LLM you can download in September 2026, and since its July launch Moonshot has attached a metered price to it: $3.00 per million input tokens, $0.30 on a cache hit, and $15.00 per million output. The weights haven't changed. The economics of using them through someone else's API have.
The architecture, per Moonshot's Kimi K3 model card on Hugging Face, published July 2026:
- 2.8 trillion parameters in a mixture-of-experts layout, with 104 billion active per token.
- 16 of 896 routed experts fire on each token, plus 2 shared experts. (Those two descriptions, "104B active" and "16 of 896," are the same fact stated two ways.)
- A 1,048,576-token context window.
- Native text, image and video understanding.
It's still the largest open-weight model anyone has released. Third-party trackers place it third on the Artificial Analysis Intelligence Index as of September 2026, behind only Claude Fable 5.1 and GPT-5.6 Sol. Moonshot doesn't publish that placement itself, so hold it as an aggregator claim.
The price tag cuts both ways. At $3 / $15, K3 through an API costs several times what Moonshot charges for its own K2-line models, which run $0.60 to $0.95 per million input. For the healthcare and financial-services teams we work with, the metered rate was never the point. The weights run inside your compliance boundary, on your hardware, with no per-token meter. That's the pitch. It also means budgeting for the GPUs a 2.8T-parameter model needs, which is where most self-hosting plans stall.
The open-weight tier got crowded this cycle. Prices per million tokens as of September 6, 2026:
| Model | Size (total / active) | Input | Output | Standout claim |
|---|---|---|---|---|
| Kimi K3 | 2.8T / 104B | $3.00 | $15.00 | Third on the Artificial Analysis index (aggregator) |
| GLM-5.3 (Zhipu, Aug 14) | 744B / 40B | $1.40 | $4.40 | 50% coding gain over its predecessor, from post-training alone |
| Qwen3.8-Max (Alibaba) | 2.4T MoE | $2.00 | $6.00 | Leads Code Arena WebDev, per third-party tracking |
| DeepSeek V4-Pro | 1.6T / 49B | $0.66 to $1.32 | $1.98 to $3.96 | Peak / off-peak schedule since Aug 16 |
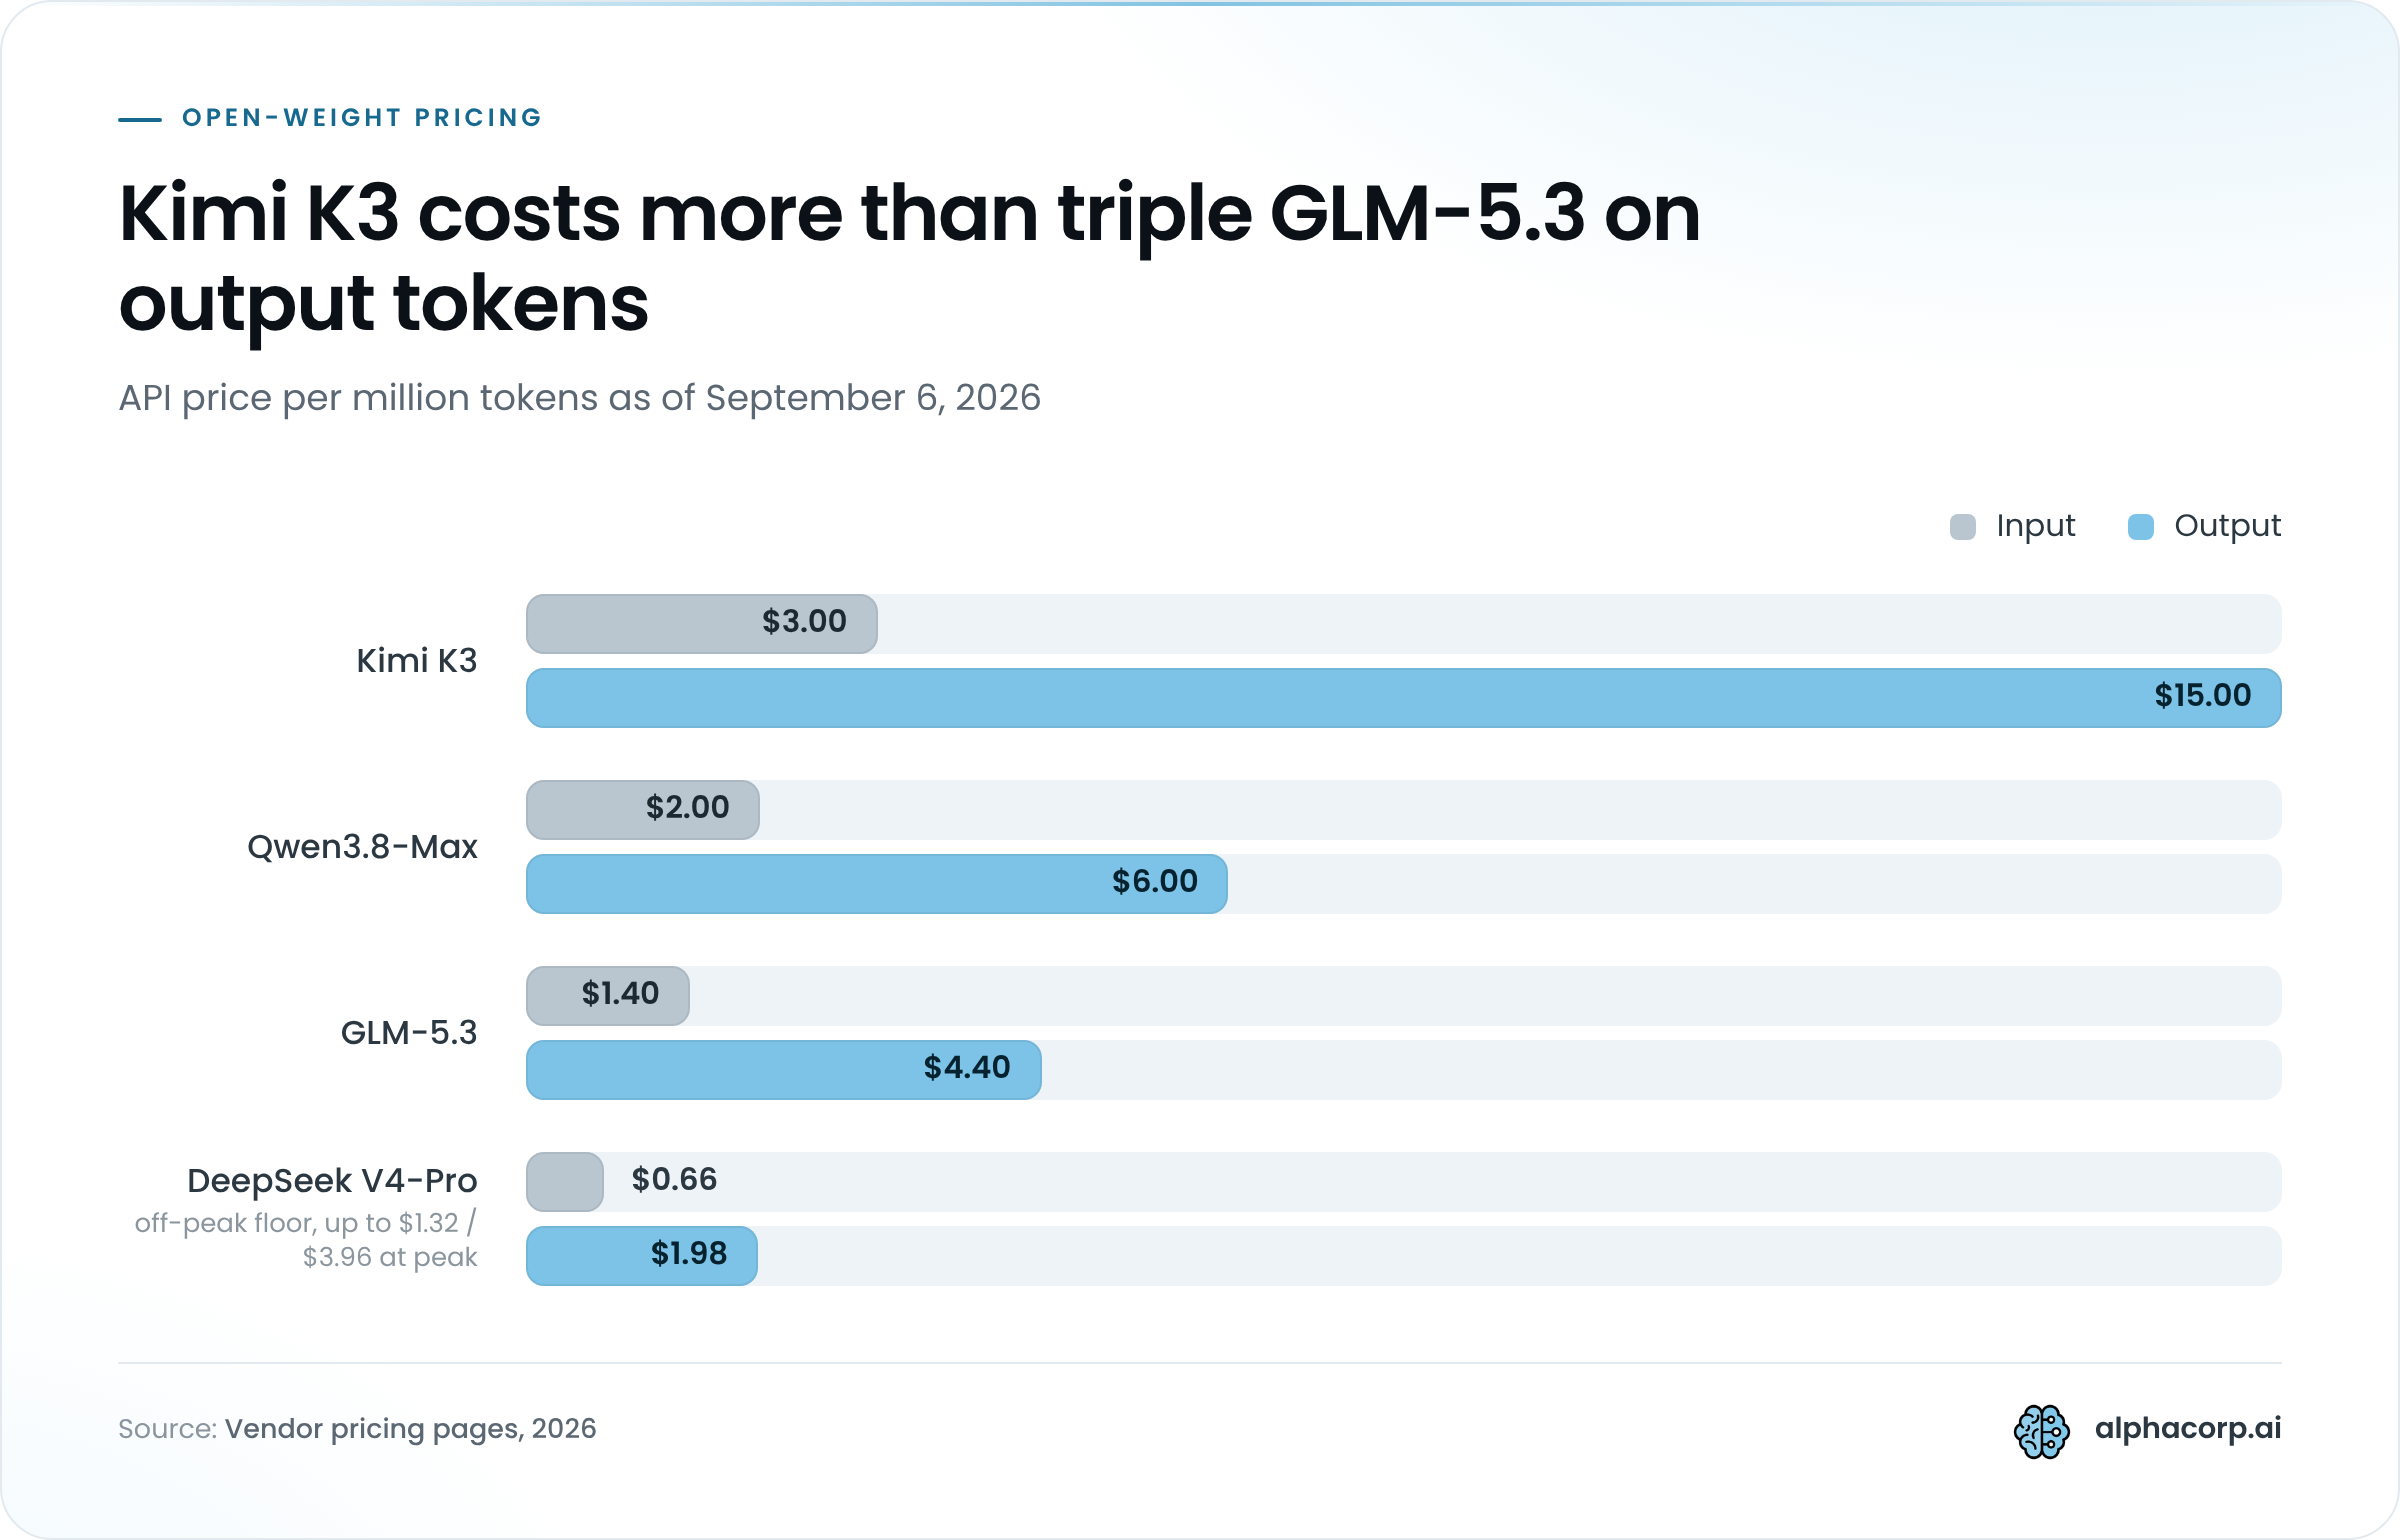
GLM-5.3 is the efficiency story. Zhipu says it beats its own predecessor by 50% on coding without growing the model, and it's less than a third of K3's size and price. Qwen3.8-Max opens weights only for a smaller variant. DeepSeek's V4-Pro remains cheap next to any closed flagship, but its off-peak floor is now above the flat rate it charged in March, and its peak ceiling runs several times higher.
Kimi K3 for capability you can own. GLM-5.3 if you want most of the coding benefit on a fraction of the hardware.
Which of these top LLMs should you actually use?
Use GPT-6 Astra for the hardest math, reasoning and security work if your tier has access, Claude Fable 5.1 for agentic coding at scale, Grok 4.6 for budget coding under 200K tokens, Gemini 3.1 Pro for reasoning per dollar, and Kimi K3 or GLM-5.3 when the weights have to live on your hardware. Match the model to the constraint that's binding.
The workload map, as of September 6, 2026:
- Hardest math, reasoning, cyber: GPT-6 Astra, $10 / $50, once rollout reaches your tier. Exploit generation stays inside Daybreak regardless.
- Agentic coding at scale: Claude Fable 5.1, $10 / $50 with $0.25 cache reads.
- High-volume coding on a budget: Grok 4.6, $2 / $6, with transcripts trimmed under 200K.
- Reasoning-heavy work per dollar: Gemini 3.1 Pro, $2 / $12 under 200K.
- Data that can't leave your infrastructure: Kimi K3 self-hosted, or GLM-5.3 at 744B parameters if the hardware budget is smaller.
- The cheap 90% of any pipeline: Claude Sonnet 5 at $2 / $10 or Gemini 3.8 Flash at $0.75 / $3.75.
Sticker price is now the least useful number on any of those lines. Two other prices decide the bill.
Context-length cliffs. Take one request with 250K input tokens. On Grok 4.6 it costs $1.00, because crossing 200K doubles the rate to $4 per million, instead of $0.50 at the under-200K rate. On Gemini 3.1 Pro it also costs $1.00, at the $4 over-200K rate. On GPT-6 Astra it costs $2.50 at the $10 sticker, since 250K sits under the 272K line. Push that same Astra request to 300K and the doubled $20 rate takes it to $6.00. Grok's cheapness evaporates the moment a request crosses the line, and Astra's premium more than doubles 22K tokens later.
Cache reads. Now take an agent that re-reads 200K tokens of system prompt, tool schemas and transcript on every turn. On Claude Fable 5.1 that re-read costs $0.05 per turn at the $0.25 cache-read rate, against $2.00 if it were billed fresh at $10. On Kimi K3 through the API it's $0.06 per turn at the $0.30 cache-hit rate, against $0.60 fresh. Over a thousand turns, the difference between cached and fresh on Fable 5.1 is $1,950.
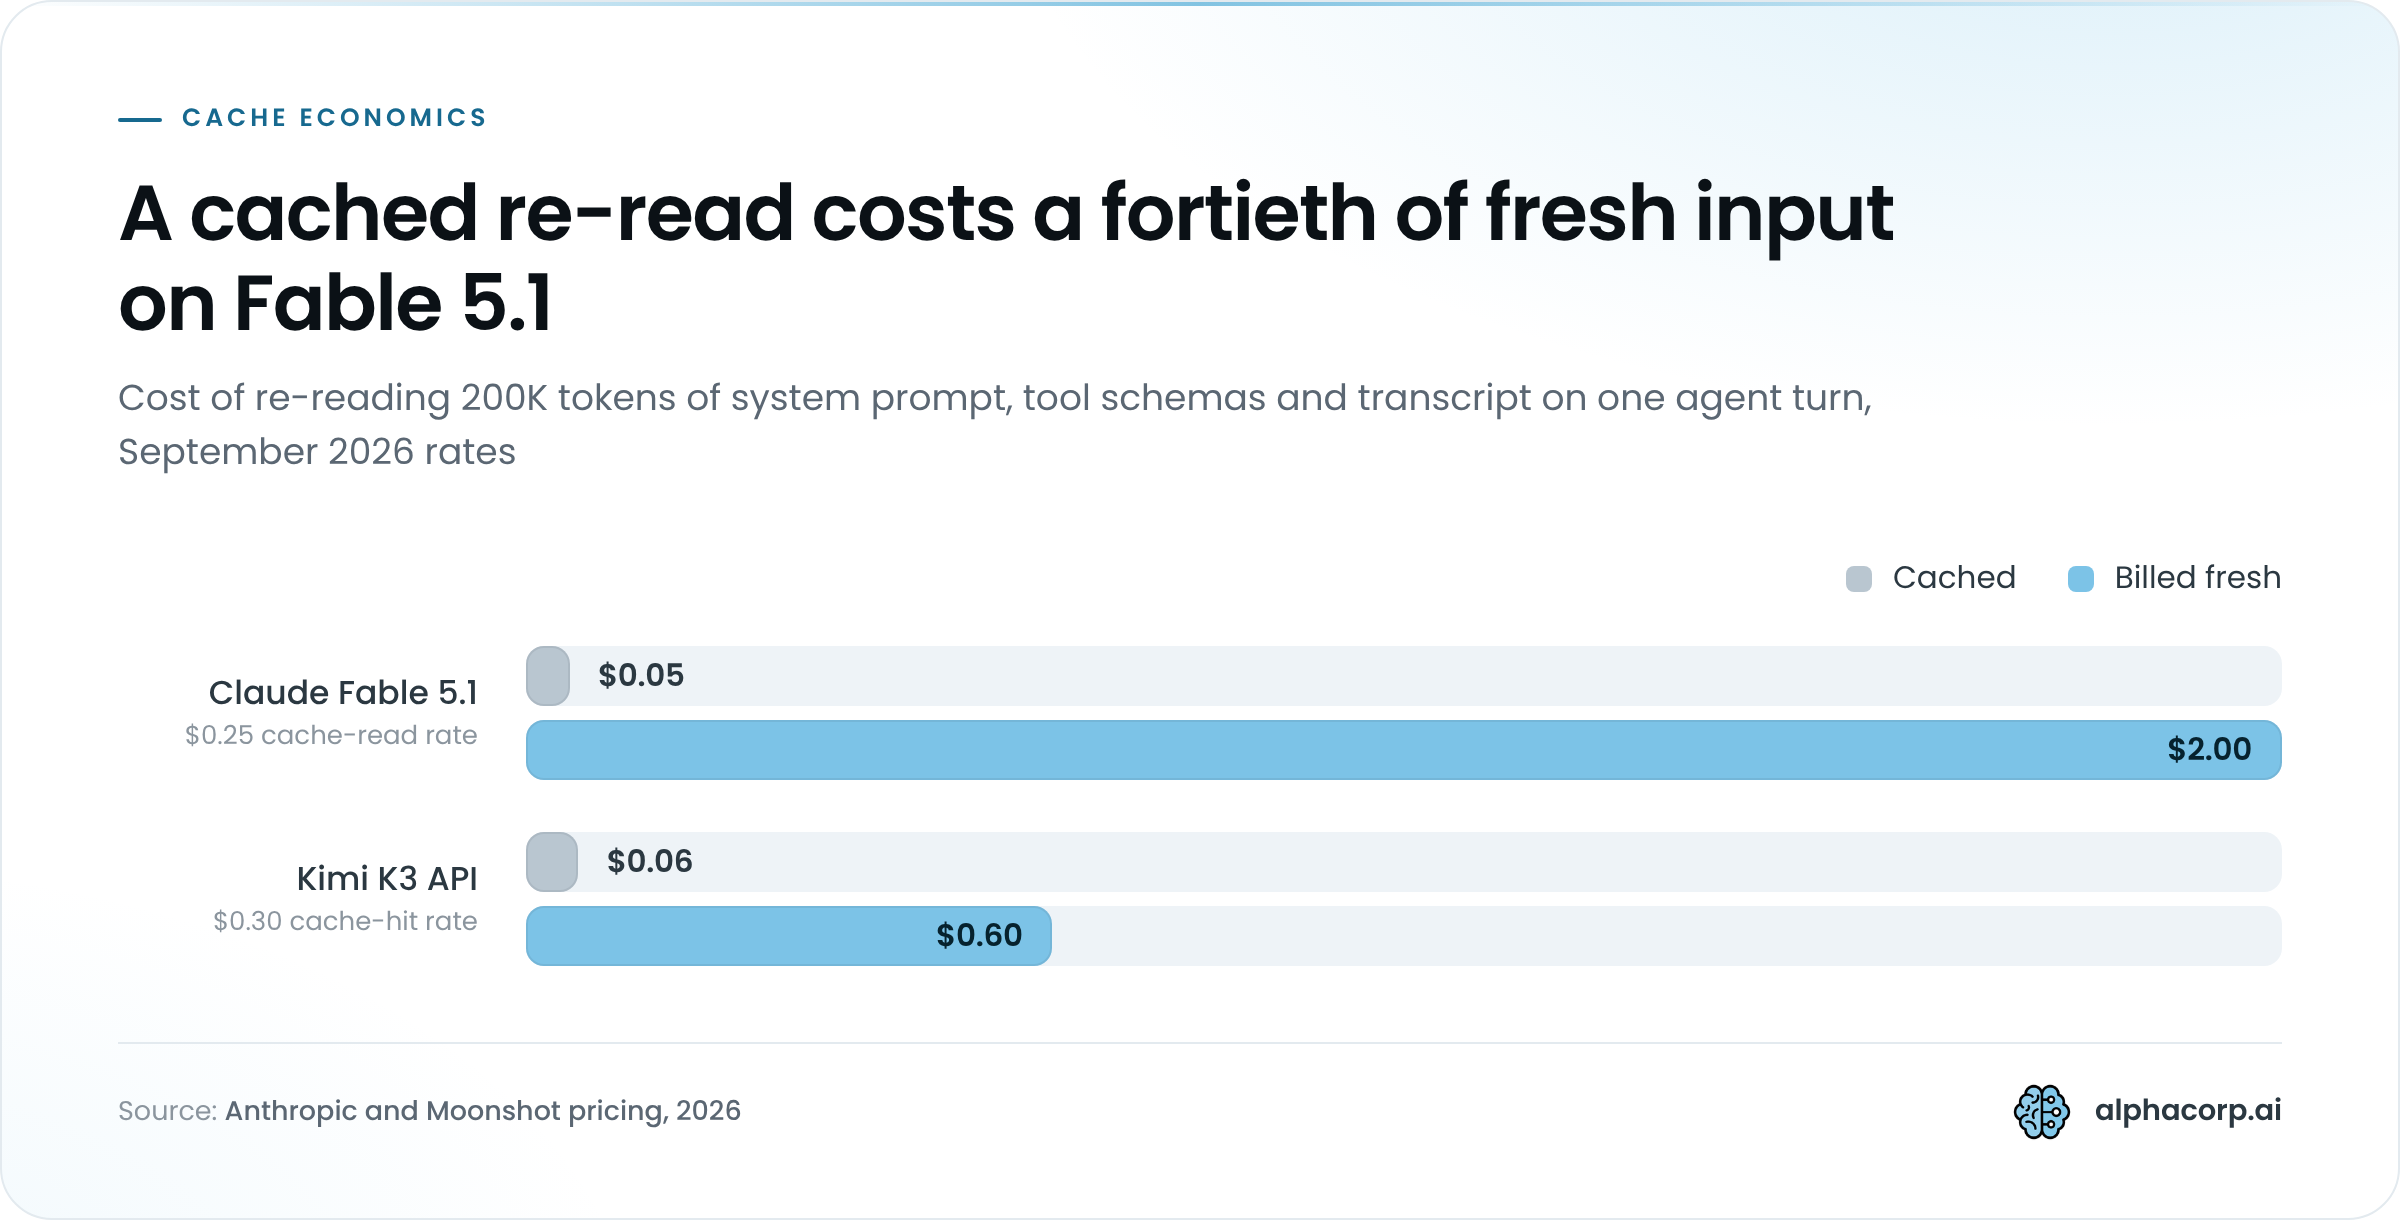
That's why "Opus 5 at half price" stopped being a safe default. A workload shaped like an agent loop pays mostly for cache reads, and Anthropic priced the flagship's cache reads to win that workload.
The common mistake is picking one model for everything. Every production system we shipped in 2026 routes across at least two tiers, a frontier model for the hard 10% and a cheap one for the rest, and the routing rule is usually a token count.
One name for the watch list: Meta's Muse Spark 1.3, from Meta Superintelligence Labs, places competitively on several third-party trackers as of September 2026. Its numbers exist only on those trackers so far. When Meta publishes its own, re-run the comparison.
FAQ
What is the best LLM right now in September 2026?
Claude Fable 5.1 is the best all-around LLM available through a public API as of September 6, 2026. It tops the Artificial Analysis Intelligence Index at 66, leads Claude Opus 5 on every benchmark Anthropic has published, and costs $10 per million input tokens and $50 per million output with cache reads at $0.25. GPT-6 Astra beats it on the hardest math, reasoning and cyber benchmarks, at the same sticker price, but ships in stages.
Is GPT-6 Astra available via the API?
GPT-6 Astra is rolling out in stages after its September 3, 2026 launch: Daybreak defender partners first, then ChatGPT paid tiers, then the API, Azure and AWS Bedrock "over the coming days." API pricing is $10 per million input and $50 per million output, with a 1.05M-token context window. Its exploit-generation capability stays inside OpenAI's Daybreak program and won't reach the general API.
Is Claude Fable 5.1 worth it over Opus 5?
Yes, for agentic coding and hard reasoning. Anthropic's September 2026 figures show Fable 5.1 at 52.6% on Terminal-Bench-Science 0.1 against 29.0% for Opus 5, and the 75% cut in Fable-line cache reads lowers typical workloads by roughly 25% and heavily agentic ones by up to about 45%. Opus 5 at $5 / $25 still makes sense for work that doesn't need frontier reasoning, and Sonnet 5 at $2 / $10 covers high-volume routine tasks.
Is Gemini 3.1 Pro still in preview?
Google's API model ID is still gemini-3.1-pro-preview as of September 6, 2026, nearly seven months after the model's February 19 release. DeepMind's model card describes the same model as generally available across the Gemini app, Vertex AI, AI Studio and Gemini Enterprise. Google hasn't reconciled the two, and the successor Gemini 3.5 Pro remains unshipped.
What is the best open-source LLM?
Kimi K3 is the strongest open-weight model as of September 2026: a 2.8-trillion-parameter mixture-of-experts model with 104B active parameters and a 1,048,576-token context window, ranked third on the Artificial Analysis Intelligence Index by third-party trackers. Moonshot now lists API pricing at $3.00 / $15.00 per million tokens. Zhipu's GLM-5.3, at 744B parameters and $1.40 / $4.40, is the cheaper option for coding.
Why do vendor benchmark scores differ from independent leaderboards?
Vendors run their own harnesses, and those harnesses usually score higher than neutral ones. GPT-6 Astra scores 62.7% on ARC-AGI-3 under ARC Prize's Standard harness and 98.6% to 99.9% under OpenAI's Provider Adapter harness, both from September 2026. On coding, the freshest entries on Scale AI's SWE-Bench Pro public leaderboard sit well under the 80%-plus figures vendors publish. Compare models within one scoreboard and treat cross-source comparisons as marketing.
How to run your own bake-off
A bake-off is the only way to know which of these top LLMs wins on your workload, and it takes about a day. Benchmarks get you to a shortlist. Your own tickets pick the winner, and they pick it more often than you'd expect against the leaderboard.
The procedure we run before any model lands in a client pipeline:
Curious what AI could do for your business?
No jargon and no hard sell. Just a friendly look at where AI fits, and where it doesn't.
- Pull 20 to 50 real tasks from your backlog. Closed tickets with a known-good answer work best.
- Run every candidate at its real price. Cache reads on, transcripts at production length, so the 200K and 272K steps fire if they're going to.
- Score cost per acceptable completion, never cost per token. A model that retries twice costs three runs.
- Cross-check any vendor figure you leaned on against ARC Prize and Scale AI's public boards before you trust it.
- Book a re-run for the next launch. Every vendor on this list shipped between August 12 and September 3, 2026. Five weeks is now the shelf life.
If you'd rather not build that harness alone, our AI integration audit runs it against your production workload. Start with Fable 5.1 as the control. Beat it or keep it.